Everyone in business has encountered an industry award that felt meaningless. Maybe it was the “prestigious” recognition that went to whoever paid the highest sponsorship fee. Maybe it was the innovation award given to the same enterprise vendor for the fifth consecutive year. Maybe it was the ceremony where half the room won something, and winning felt less like achievement than attendance.
The cynicism around industry awards is earned. Too many programs operate as revenue engines first and recognition systems second. Too many winners are predictable before judging begins. Too many categories exist to create more entry fees rather than meaningful distinctions. This creates a problem for everyone.
Organisers running legitimate programs compete against a backdrop of scepticism. Companies with genuine achievements struggle to leverage recognition that audiences dismiss. And the entire concept of industry awards, which should identify excellence and help buyers make better decisions instead gets undermined by programs that treat credibility as optional.
The good news…credibility isn’t mysterious. Awards programs lose trust in predictable ways, which means those failures can be avoided. Understanding how credibility erodes is the first step toward building programs that actually mean something.
Why credibility loss matters
Programs can lose credibility while maintaining entry volume. Companies enter awards for many reasons, checkbox marketing, competitive pressure, executive vanity, that don’t require believing the award means anything.
But credibility loss has real costs, even when entry numbers mask the problem.
Winner value diminishes. When audiences don’t trust an award, winners can’t leverage it effectively. “Award-winning” becomes noise rather than signal. Companies stop promoting wins because doing so invites eye-rolls rather than respect.
Quality of entries declines. Serious organisations stop participating when they perceive programs as pay-to-play or popularity contests. Entry volume might hold, but entry quality hollows out as credible players exit.
Sponsorship becomes harder. Sophisticated sponsors evaluate whether association with an award enhances or diminishes their brand. Programs with credibility problems attract sponsors seeking logo placement, not partners seeking quality association.
Pricing power erodes. Credible awards command premium entry fees because winning delivers real value. Programs perceived as selling recognition rather than evaluating it face constant pricing pressure.
Long-term sustainability weakens. Awards programs depend on network effects, past winners promoting their recognition, judges lending their reputations, sponsors seeking association with excellence. When credibility erodes, these virtuous cycles reverse into decline spirals.
Entry numbers are lagging indicators. Credibility problems often become visible in participation data only after the underlying damage is severe.
The seven ways awards programs lose credibility
Credibility doesn’t disappear overnight. It erodes through specific, identifiable failures, often ones that seem minor individually but compound over time.
1. Pay-to-Play perception
The most damaging perception an awards program can acquire: winners are determined by spending, not achievement.
This perception takes multiple forms:
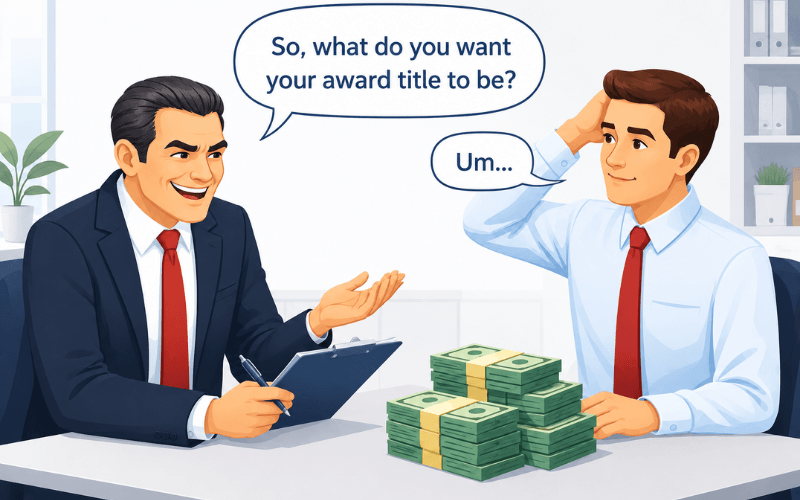
The most blatant manifestation: organisers offering companies the opportunity to “pick their own title” for a fixed fee. Industry observers have documented instances of bespoke awards, “Best Whatever You Want”, available for purchase rather than competition. This isn’t recognition; it’s a retail transaction for a marketing asset.
Entry fee correlation. When winners consistently come from organisations that entered the most categories or paid the highest fees, patterns become visible. Even if fee payment genuinely doesn’t influence judging, the appearance of correlation is enough to seed doubt.
Sponsorship overlap. When major sponsors win major awards in the same program they sponsor, scepticism is inevitable. It doesn’t matter whether firewalls exist between sponsorship and judging, audiences assume influence.
Premium entry tiers. Programs offering “enhanced” entry packages with additional judge access, feedback sessions, or promotional benefits blur the line between paying for services and paying for outcomes.
Everyone wins something. When programs create enough categories that most entrants receive recognition, the economics become transparent: entry fees purchase awards, with “judging” as theatre.
Pay-to-play perception is particularly sticky. Once an audience believes a program sells awards, evidence to the contrary rarely changes minds.
2. The same winners every year
Predictable winners signal that evaluation isn’t really happening.
The “guaranteed shortlist” tactic reveals the game. When a category receives nine entries and all nine are shortlisted, finalist status becomes a hollow marketing mirage designed to sell table bookings. If you submit and pay, you’re shortlisted. The “competition” is theatre.
When the same large enterprise wins “Innovation of the Year” repeatedly, audiences reasonably conclude that brand recognition outweighs actual innovation assessment. When the same agency dominates creative categories across multiple programs, the awards start reflecting incumbent advantage rather than annual excellence.
Some repeat winning is legitimate, genuinely excellent organisations may sustain excellence. But patterns matter:
- Do winners correlate with company size more than achievement quality?
- Are the same organisations winning across completely different criteria?
- Do smaller entrants ever beat larger, better-known competitors?
Credible awards produce some surprises. When outcomes are entirely predictable, something other than rigorous evaluation is determining results.
3. Opaque or non-existent judging
If you can’t explain how winners were selected, audiences will assume the worst. Credibility requires that participants and observers understand:
- Who judges entries (names, credentials, independence)
- What criteria judges apply (specific, published standards)
- How scores translate to outcomes (methodology transparency)
- What prevents bias or conflicts (safeguards and recusals)
Programs that keep judging invisible, hiding judge identities, refusing to discuss methodology, providing no feedback to entrants, invite suspicion that rigorous evaluation didn’t occur.
This doesn’t mean publishing complete scorecards. It means providing enough transparency that a skeptical observer could conclude the process was legitimate even if they disagree with specific outcomes.
4. Sponsor influence (real or perceived)
Sponsors are essential to many awards programs. Sponsor influence over outcomes destroys credibility.
The problem isn’t just actual influence, it’s the appearance of influence:
- Sponsors winning in categories they sponsored
- Sponsor executives serving as judges
- Sponsor logos more prominent than winner announcements
- Categories that seem designed around sponsor product areas
- Programs where non-sponsors rarely win premium categories
Some of these situations can be managed through rigorous firewalls and transparent policies. Others should simply be prohibited. When sponsor relationships and judging processes have any visible intersection, audiences assume the worst.
Programs must choose: maximise short-term sponsor revenue by allowing potential influence appearances, or protect long-term credibility by maintaining absolute separation. There is no middle ground that sophisticated audiences will trust.
5. Categories that don’t make sense
Category design signals how seriously a program takes recognition.
Warning signs include:
Overlapping categories. When “Digital Innovation,” “Technology Excellence,” and “Digital Transformation” all exist in the same program, the purpose seems to be multiplying entry fees rather than creating meaningful distinctions.
Vanity categories. Categories so broadly defined that almost anyone could enter, and many could win, suggest the goal is selling recognition rather than identifying excellence.
Sponsor-shaped categories. Categories that appear designed around a sponsor’s product positioning rather than natural industry distinctions reveal commercial priorities.
Category proliferation. Adding categories year over year without retiring underperforming ones signals revenue optimisation, not program refinement.
Credible programs have categories that make sense to practitioners, distinctions they’d naturally draw when discussing excellence in their field. When categories feel arbitrary or commercially motivated, credibility suffers.
6. Winners that surprise no one (or everyone)
Judging outcomes signal whether real evaluation occurred.
When winners surprise no one it signals that every award goes to the largest, best-known, or most-expected recipient. Results could have been predicted from market share data alone. The judging process appears to have confirmed conventional wisdom rather than evaluated actual entries.
When winners surprise everyone it signals that results seem random, disconnected from visible quality or achievement. Unknown entities win over obviously strong competitors. Outcomes appear arbitrary rather than rigorously determined.
Credible judging produces outcomes that feel earned, explicable in retrospect even if not entirely predictable in advance. “I wouldn’t have guessed them, but now that I see their submission, I understand why they won” represents healthy judging outcomes.
When outcomes feel predetermined or inexplicable, audiences discount the evaluation process entirely.
7. Overpromising, underdelivering
Awards programs often oversell the value of recognition:
- Promising media coverage that doesn’t materialise
- Implying industry-wide prestige that doesn’t exist
- Suggesting winner benefits that arrive diminished or never
- Claiming rigorous judging that entrants experience as superficial
When winner experience doesn’t match promotional claims, disillusionment spreads. Winners talk to each other. Disappointed past winners become vocal critics. Word spreads that the program overpromises.
This credibility damage extends beyond individual disappointed winners. When a program develops a reputation for underdelivering, even strong execution struggles against established scepticism.
The compounding problem: how small compromises become big credibility gaps
Credibility rarely collapses from a single decision. It erodes through accumulated compromises that each seem minor in isolation.
A sponsor requests that their executive join the judging panel, just one judge among many, properly managed for conflicts. A small accommodation.
Entry volume disappoints, so a few additional categories are created to attract more submissions. Reasonable business management.
A major entrant questions their score, and to maintain the relationship, detailed feedback that wasn’t planned gets provided. Good customer service.
A past winner with strong industry relationships is entered in a category where they’re borderline eligible. Enforcing strict disqualification seems unnecessarily rigid.
Each decision is defensible individually. Together, they create patterns that observant audiences notice. Small accommodations accumulate into systemic credibility problems.
This compounding effect makes discipline essential. Programs that bend rules for good reasons repeatedly find their credibility bent out of shape.
How to build (or rebuild) credibility
If credibility is designed rather than declared, the design elements are identifiable.
Make judging visible
Name your judges. Publish their credentials and independence. Explain your methodology in enough detail that sceptics could evaluate whether it’s rigorous. Describe conflict management explicitly.
You don’t need to reveal individual scores or deliberations. You need to demonstrate that qualified people applied legitimate criteria through defensible processes.
Separate sponsors from outcomes
Absolute firewalls between sponsorship and judging. No sponsor executives as judges. No sponsor visibility into submissions. Consider prohibiting sponsors from entering categories they sponsor, or at minimum, document and publish the separation policies.
The sponsorship wall.
Establish a non-negotiable rule: sponsors are ineligible for awards they fund. This removes pay-to-play perception entirely. The branding benefit of sponsorship should not translate into unearned trophies.
Verification over narrative.
Move away from marketing pitches. Where possible, incorporate hard metrics, database audits, and verifiable performance data. Show excellence rather than describe it.
Defense, not just submission.
Some programs require finalists to defend their claims in front of panels, not hide behind polished PR documents. This interview-based verification filters substance from spin
Design categories that make sense
Create distinctions practitioners would recognise. Ensure entries within categories are genuinely comparable. Remove or merge categories that don’t attract meaningful competition. Resist the temptation to proliferate categories for revenue.
Accept fewer winners
Not everyone can win. Meaningful recognition requires selectivity. When programs recognise too many entrants, each recognition means less. The courage to have losers is essential to having credible winners.
Verify what you can
Claims in submissions should be validated to the extent feasible. Spot-check key assertions. Contact customer references. Require documentation for financial claims. You don’t need to verify everything, but demonstrable verification effort signals seriousness.
Deliver what you promise
If you claim media coverage, deliver it. If you promise networking value, create it. If you describe prestigious judging, execute it. Underpromising and overdelivering builds reputation far more effectively than marketing claims that reality doesn’t support.
Solicit and act on feedback
Ask entrants, judges, and winners what’s working and what isn’t. When feedback reveals problems, fix them. Programs that visibly improve based on input demonstrate that credibility matters to them.
The credibility test: questions to ask about your own program
Honest assessment requires uncomfortable questions.
About perception:
- If a journalist investigated your judging process, would you be comfortable with what they’d find?
- Would winners enthusiastically recommend entering to respected peers?
- Do losing entrants believe they lost fairly?
About process:
- Can you explain exactly how winners are determined to a sceptical audience?
- Could a conflict of interest exist that you haven’t identified?
- Would your judging methodology survive scrutiny from someone looking to criticise it?
About patterns:
- Do your winners correlate more with entry fees and company size or with submission quality?
- Could an outsider predict your winners before judging based on brand recognition alone?
- Are there entrants who should be winning but aren’t, or winners who shouldn’t be but are?
About incentives:
- If a major sponsor threatened to withdraw unless they won, what would you do?
- Are there decisions you’ve made that you wouldn’t want publicised?
- Is your revenue model compatible with saying “no” to paying participants?
If these questions make you uncomfortable, the discomfort is diagnostic.
When credibility is gone: can you get it back?
Rebuilding credibility is harder than building it initially. Once audiences decide a program lacks integrity, evidence to the contrary faces severe scepticism. Recovery requires:
Acknowledge the problem. Not vague commitments to improvement, but specific identification of what went wrong. Audiences respect honesty about past failures more than pretending problems didn’t exist.
Make visible structural changes. If sponsor influence was the problem, announce and implement strict separation policies. If judging was opaque, publish your methodology. Changes must be concrete and verifiable, not just claimed.
Accept the timeline. Credibility rebuilds over years, not cycles. Consistent, trustworthy execution across multiple program years gradually shifts perception. One clean year doesn’t erase accumulated scepticism.
Let others validate. Your claims of reform matter less than external validation. Judges, winners, and industry observers who independently confirm improvements carry more weight than your marketing.
Consider rebranding. In severe cases, the program name itself carries too much negative baggage. A fresh start under a new identity, with genuinely reformed practices, sometimes succeeds where rehabilitation fails.
Some programs successfully rebuild credibility. Many don’t, the accumulated damage proves permanent, and the program slowly fades as credible alternatives emerge.
The lesson: protecting credibility is easier than restoring it. The time to care about trust is before it’s gone.
Conclusion
Awards programs lose credibility in predictable ways, which means those failures can be avoided. The seven patterns are consistent: pay-to-play perception where winners correlate with spending rather than achievement; the same winners every year signalling that evaluation isn’t really happening; opaque judging that invites audiences to assume the worst; sponsor influence, real or perceived, where sponsorship relationships intersect with outcomes; categories that don’t make sense and seem designed for revenue rather than recognition; winners that surprise no one (confirming market share rather than evaluating entries) or everyone (appearing arbitrary rather than rigorous); and overpromising value that reality doesn’t deliver.
These failures rarely happen through single dramatic decisions. Credibility erodes through accumulated compromises that each seem minor, a sponsor executive joining the panel, a few extra categories to boost entries, flexible eligibility for a well-connected entrant, until small accommodations have compounded into systemic problems that observant audiences notice.
Building or rebuilding credibility requires structural commitments, not declarations. Make judging visible by naming judges, publishing methodology, and explaining conflict management. Establish absolute firewalls between sponsors and outcomes, consider making sponsors ineligible for awards they fund, because the appearance of separation matters as much as actual separation. Design categories practitioners would recognise rather than proliferating for revenue. Accept that meaningful recognition requires selectivity, because the courage to have losers is essential to having credible winners. Verify claims in submissions to the extent feasible rather than letting marketing narratives go unchecked.
Deliver what you promise, because disappointed winners become vocal critics. And ask yourself the uncomfortable questions: if a journalist investigated your process, would you be comfortable with what they’d find? Could an outsider predict your winners before judging based on brand recognition alone? Is your revenue model compatible with saying “no” to paying participants? If these questions make you uncomfortable, the discomfort is diagnostic, and the time to care about trust is before it’s gone.
→ How to Design a Credible Awards Program : The complete guide to building awards programs with credibility designed in from the start.
→ Managing Conflicts of Interest in Awards Judging : Systematic approaches to identifying, disclosing, and managing the conflicts that undermine trust.
→ How to Define Award Categories That Actually Work : Category design that creates meaningful distinctions rather than revenue-driven proliferation.
→ Award Judging Models Explained : Understanding how different judging approaches affect credibility and perception.
Frequently Asked Questions
Pay-to-play perception forms when audiences believe spending, not achievement, determines outcomes. It can be triggered by patterns such as sponsors winning major awards in the same program they fund, winners clustering among companies that enter the most categories, or “premium” entry tiers that blur paying for services with paying for results.
The most damaging versions are overt retail-style offers (bespoke titles for a fee) or “everyone wins something” structures where category volume makes the economics feel obvious. Once people believe awards are sold, reversing that perception is extremely difficult.
Repeated winners can be legitimate, but predictability signals that evaluation may not be meaningfully differentiating year to year. When the largest, best-known brands repeatedly take “Innovation of the Year,” or when finalist lists match entry lists because all entrants are shortlisted, audiences infer that brand gravity or pay-to-enter mechanics outweigh annual excellence.
Credible programs produce at least occasional surprises, smaller entrants beating incumbents, because the process is judging submissions, not confirming market dominance.
Trust requires explainable judging, not full disclosure of deliberations. A credible baseline includes: who the judges are (names and credentials), what criteria they apply (published standards), how decisions are made (scoring and aggregation approach), and how conflicts of interest are handled (recusals and safeguards).
When judging is invisible, no judge identities, no methodology, no criteria, audiences assume the worst, even if the process is legitimate behind the scenes.
Sponsor influence is often reputational before it’s procedural. If sponsors win in categories they sponsor, sponsor executives judge, or categories appear shaped around sponsor positioning, audiences assume outcomes are compromised, regardless of internal firewalls.
Credibility protection typically requires visible separation: sponsors kept away from judging, no access to submissions, and clear policies that remove even the appearance of influence.
Common warning signs include overlapping categories that attract the same entries (“Digital Innovation,” “Technology Excellence,” “Digital Transformation”), vanity categories so broad almost anyone qualifies, sponsor-shaped categories that mirror commercial positioning, and category proliferation year after year without retiring weak categories.
When categories feel arbitrary or commercially motivated rather than practitioner-meaningful, audiences conclude the program is selling more entry slots, not making meaningful distinctions.
If winners surprise no one, the results look predetermined, largest brand wins, conventional wisdom confirmed, making judging feel like theatre. If winners surprise everyone, outcomes look random or disconnected from visible quality, which suggests the evaluation process is inconsistent or ungrounded.
Healthy judging produces outcomes that are defensible in retrospect: not always predictable, but explainable once people understand what was submitted and how it was assessed.
It happens when programs market prestige and benefits they don’t actually provide, promised media coverage that never appears, winner perks that arrive diminished, or claims of rigorous judging that entrants experience as superficial.
This spreads quickly because winners talk to each other. When winner experience doesn’t match promotional claims, the program develops a reputation that is hard to overcome even if execution later improves.
Credibility rebuilds through visible design choices: make judging visible (judges, criteria, methodology, conflicts process), separate sponsors from outcomes with hard firewalls, verify claims where feasible (spot checks, reference calls, documentation for key assertions), and reduce “everyone wins” dynamics by being selective.
Category discipline matters too: merge or remove weak or overlapping categories and ensure each category creates a comparable field. These changes signal seriousness because they reduce revenue-optimised shortcuts.
Recovery is more likely when organisers acknowledge specific failures, implement concrete and verifiable structural reforms, and execute consistently across multiple cycles. Trust shifts gradually only after repeated evidence that incentives, rules, and processes have changed.
External validation matters more than organiser messaging. Judges, winners, and respected observers confirming that the program is now rigorous carries more weight than claims of improvement from the program itself.