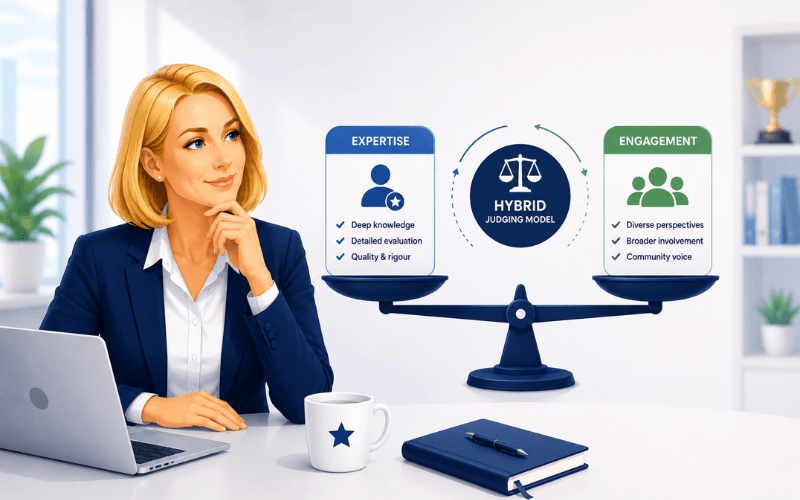
Pure expert judging delivers credibility but limited engagement. Pure public voting drives participation but may not identify genuine excellence. Many programs want both, the legitimacy that comes from expert evaluation and the visibility that comes from audience involvement.
Hybrid models attempt to deliver this combination. They bring expert judges and public audiences together in a single evaluation framework, giving each a defined role in determining outcomes. When designed well, hybrids capture the strengths of both approaches while managing their limitations. When designed poorly, they satisfy neither constituency and create confusion about what winning actually means.
The challenge isn’t whether to combine expert and public input, it’s how to combine them in ways that produce clear, defensible, meaningful outcomes. This guide covers the main hybrid structures, how to choose between them, and how to design hybrids that work rather than compromise.
Why hybrid models exist
Hybrid models emerge from competing pressures that pure approaches can’t satisfy alone.
Credibility pressure
Programs need outcomes that audiences trust. When winners clearly don’t represent excellence, when they won on audience size alone, credibility suffers. Expert involvement provides quality assurance that pure voting can’t deliver.
Engagement pressure
Programs need participation and visibility. Expert-only judging happens behind closed doors. Audiences don’t engage. Entrants don’t promote. The program lacks the reach that public involvement generates.
Stakeholder pressure
Different stakeholders want different things. Sponsors may want engagement metrics. Industry bodies may want credible outcomes. Entrants may want fair evaluation. Audiences may want voice. Hybrid models attempt to satisfy multiple constituencies rather than choosing one over others.
Positioning pressure
Programs positioned as both prestigious and accessible face tension between those identities. Pure expert judging signals prestige but exclusivity. Pure voting signals accessibility but questionable standards. Hybrids attempt to occupy middle ground.
These pressures are real, and hybrid models can address them. But hybrids that simply split the difference without clear design produce muddled results. The goal is integration, not compromise.
The main hybrid structures
Several distinct approaches exist for combining expert and public input. Each has different characteristics and fits different purposes.
Weighted combination
Expert scores and public votes each contribute a defined percentage to final results. An entry’s final standing reflects both inputs according to predetermined weightings.
How it works: Judges score entries on a standardised scale. Public votes are counted and converted to a comparable scale. The two scores are combined according to the stated weighting, perhaps 70% judge score plus 30% public vote, to produce final rankings.
- Strengths: Both inputs genuinely influence outcomes. The balance between expertise and engagement is explicit and adjustable.
- Results can be explained clearly.
- Weaknesses: The mathematics of combination can produce unexpected results. Entries might win without topping either judging or voting. Weightings may feel arbitrary if not clearly justified.
- Best for: Programs wanting both inputs to matter for the same recognition, with clear control over relative influence.
Sequential filtering
Experts evaluate first and select finalists. Public voting then determines winners from among qualified options.
How it works: Judges review all entries and advance the strongest to a shortlist. Only shortlisted entries proceed to public voting. The finalist with the most votes wins.
- Strengths: Quality floor is guaranteed, only entries judges deemed worthy can win. Public voice is meaningful but constrained to credible options. Judges aren’t overruled by popularity.
- Weaknesses: Public voting may still advantage larger audiences among finalists. Judges do substantial work without determining final outcomes. Finalists who lose in voting may feel judging endorsement was meaningless.
- Best for: Programs where credibility requires quality assurance but where final recognition should reflect audience preference.
Parallel tracks
Expert judging and public voting run independently, producing separate recognitions.
How it works: Judges evaluate entries and select winners for official categories. Simultaneously, public voting selects a separate People’s Choice winner. Both recognitions are announced, each with its own meaning.
- Strengths: Each track serves its purpose purely. No confusion about what each recognition means. Winners of expert categories can’t be accused of winning on popularity; People’s Choice winners clearly won on audience support.
- Weaknesses: Programs must manage two processes and two sets of communications. Some entrants may win both; others may feel one recognition undermines the other. Resource requirements increase.
- Best for: Programs wanting to offer both types of recognition without combining them into a single, potentially muddled outcome.
Category-specific approaches
Different categories use different models based on their nature.
How it works: Technical or specialist categories use expert judging. Creative or audience-focused categories use public voting. Community recognition uses peer voting. Each category matches its evaluation method to what it’s designed to recognise.
- Strengths: Each category uses the most appropriate model. No forcing of voting onto categories where it doesn’t fit. Flexibility to optimise each recognition type.
- Weaknesses: Complexity increases. Participants must understand different rules for different categories. Program communication becomes more complicated.
- Best for: Programs with diverse category types where a single model wouldn’t serve all purposes.
Choosing weightings in combined models
If using weighted combinations, the balance between expert and public input requires deliberate decision-making.
What weightings signal
Weightings communicate priorities. A 90/10 judge/public split says experts determine outcomes and public input is token acknowledgment. A 50/50 split says both perspectives matter equally. A 30/70 judge/public split says audience preference drives outcomes with some expert floor.
Before choosing numbers, decide what message you want to send and what outcomes you want to produce.
Common weighting approaches
- 80/20 or 70/30 judge/public: Expert credibility is primary. Public voting adds engagement and modest influence without driving outcomes. Use when credibility is paramount but some audience involvement is desired.
- 60/40 judge/public: Experts lead but public input meaningfully affects results. Entries with strong public support can overcome modest judge score gaps. Use when both dimensions genuinely matter.
- 50/50: True balance. Neither judges nor public determine outcomes alone. Results reflect both inputs equally. Use when you genuinely believe both perspectives deserve equal weight, and accept that results may satisfy neither fully.
- 40/60 or 30/70 judge/public: Public preference primary with expert quality floor. Use when audience voice is the core purpose but you want judges to filter out clearly unworthy entries.
Testing weightings before committing
If possible, model how different weightings would affect outcomes using sample data. How would last year’s entries have ranked under 70/30 versus 60/40? Would the same winners emerge? Would any surprising results occur?
Modelling reveals whether your weightings produce outcomes you’re comfortable defending.
Communicating weightings clearly
Whatever weighting you choose, publish it prominently before entries open. Participants should know exactly how their input, whether as judges or voters, contributes to outcomes. Hidden or vague weightings invite suspicion and make results harder to explain.
Designing sequential models effectively
Sequential filtering, judges select finalists, public votes determine winners, requires careful design to work well.
Defining the finalist pool
How many finalists advance to voting? Too few limits meaningful choice. Too many overwhelms voters and dilutes the quality signal that judging provides.
Typically, 3–5 finalists per category works well. This provides genuine choice without excessive options. Larger pools may be appropriate for high-profile categories with strong engagement.
Communicating what judging determined
When judges select finalists, communicate what that selection means. Did judges rank entries, with the top five advancing? Did they set a quality threshold, with all entries meeting it advancing? Did they score and the top scorers automatically qualify?
This transparency helps finalists understand their standing and helps voters understand what judging already established.
Managing finalist expectations
Finalists selected by judges but not chosen by voters may feel judging endorsement was meaningless. Address this by celebrating the finalist achievement, recognition that expert judges selected them as among the best, distinct from the final winner announcement.
Some programs announce “finalists selected by our expert panel” with genuine celebration before voting opens. This establishes judging as meaningful recognition in its own right, not just a filter for voting.
Preventing voting-stage problems
All the risks of public voting, manipulation, reach advantages, gaming, apply to the voting stage of sequential models. Implement the same safeguards you would for pure voting: fraud prevention, clear rules, monitoring, and honest communication.
Designing parallel track models
Running expert judging and public voting as separate tracks requires coordination without confusion.
Clarifying what each track means
Each recognition needs a clear, distinct meaning. Expert category winners were selected by qualified judges evaluating against defined criteria. People’s Choice winners were selected by audience vote reflecting popular preference. Neither is better, they’re different.
Communicate these distinctions consistently. Don’t imply that one is more legitimate than the other unless you genuinely believe and want to communicate that.
Handling entrants who win both
When an entry wins both expert recognition and People’s Choice, celebrate the double achievement, excellence validated by both experts and audiences. This is the ideal outcome, demonstrating alignment between quality and popularity.
But be prepared for this to be rare. Often, different entries win each track, which is fine and expected. The tracks measure different things.
Handling entrants who win neither
Entries that reach finals in both tracks but win neither may feel doubly disappointed. Consider whether to communicate finalist status in both tracks as meaningful recognition, and whether to combine announcements in ways that celebrate all finalists.
Resource implications
Parallel tracks require parallel processes. Two evaluation systems, two results to manage, two sets of communications. Ensure you have capacity to run both well rather than running one well and one poorly.
Design principles for any hybrid
Regardless of which structure you choose, certain principles improve hybrid model success.
Clarity over complexity
Participants should understand how the model works without extensive explanation. If describing your hybrid takes more than a few sentences, it may be too complicated. Complexity breeds confusion and suspicion.
Test your model explanation on someone unfamiliar with your program. If they can’t quickly understand how winners are determined, simplify.
Purpose alignment
Every element of the hybrid should serve the program’s purpose. If public voting is included, it should add something meaningful, genuine audience voice, not token participation. If expert judging is included, it should provide genuine quality assurance, not rubber-stamping.
Don’t include elements for appearance without substance. Token gestures satisfy no one.
Defensible outcomes
Before finalising your model, imagine explaining any possible outcome to skeptical observers. Could you defend a winner who topped public voting but ranked fifth with judges? Could you defend a winner who topped judging but finished last in voting?
If any possible outcome would be indefensible, your model design needs adjustment.
Consistent application
Whatever rules you establish, apply them consistently across all categories and entries. No adjustments mid-process. No exceptions for important entrants. Consistency is essential for fairness and credibility.
Document rules before the process begins and resist pressure to modify them once underway.
Transparent communication
Publish your hybrid model details prominently. Explain what judges evaluate, how votes are counted, how inputs are combined, and how winners are determined. Transparency builds trust; opacity invites suspicion.
Continue transparency through results announcement. Explain how winners emerged from your process, not just who won.
Common hybrid mistakes to avoid
Vague or undisclosed weightings
Saying “judging and public voting both contribute to results” without specifying how invites skepticism. Are votes 5% or 50%? Without clarity, participants fill the gap with assumptions, often negative ones.
If you use weightings, state them. If you don’t want to state them, question whether your model is defensible.
Mismatched purposes and methods
Using public voting for technical categories where audiences can’t evaluate quality, or using expert judging for People’s Choice categories that should reflect popular preference, creates mismatch. Each evaluation method should fit what it’s evaluating.
Review each category and confirm the method matches the purpose.
Tokenistic inclusion
Including judges at 10% weighting to claim expert credibility while public voting determines outcomes fools no one. Including public voting at 10% to claim engagement while judges determine everything disappoints audiences expecting meaningful voice.
If you include an element, give it genuine weight. If you don’t want it to influence outcomes, don’t include it.
Changing rules mid-process
Adjusting weightings, finalist counts, or combination methods after entries are submitted or voting has begun destroys trust. Participants feel manipulated. Outcomes feel engineered.
Lock rules before the process begins. If problems emerge that require changes, apply them to future cycles rather than retroactively.
Complexity that obscures
Hybrids with multiple stages, varying weightings by category, different thresholds for different levels, and elaborate tiebreaker procedures become impenetrable. Even if the complexity is logical, it appears designed to obscure rather than clarify.
Simplify until participants can understand and trust the process.
Testing and refining your hybrid
Hybrid models benefit from iteration. Build in opportunities to assess and improve.
Pilot with low-stakes categories
If introducing hybrid elements to an established program, consider piloting with less prominent categories before applying to flagship awards. Learn from the pilot before full implementation.
Gather participant feedback
After each cycle, survey judges about their experience. Did they understand how their input would be used? Did outcomes reflect their evaluation? Survey voters similarly. Did they understand what they were contributing to? Did they trust the process?
Feedback reveals whether your hybrid works as intended or needs adjustment.
Review outcomes for patterns
Analyse results across cycles. Are certain types of entries systematically advantaged by your hybrid structure? Do outcomes consistently surprise or disappoint? Patterns may reveal design issues worth addressing.
Adjust deliberately
When changes are needed, make them between cycles with clear communication. Explain what’s changing and why. Frame adjustments as improvement rather than correction, unless genuine problems require acknowledgment.
Hybrid models aren’t set-and-forget. They require ongoing attention to ensure they continue serving program purposes as contexts evolve.
Making the decision
Hybrid models aren’t inherently better than pure approaches. They’re more complex, harder to communicate, and create more opportunities for confusion. Their advantage is addressing competing needs that pure models can’t satisfy alone.
Choose hybrid models when you genuinely need both expert credibility and public engagement, and when you can design a structure that delivers both clearly rather than compromising both partially.
If your primary need is credibility, expert judging may serve better. If your primary need is engagement, public voting may serve better. Hybrids work best when both needs are genuinely important and neither can be sacrificed.
Whatever you choose, design deliberately. Understand what each element contributes. Communicate clearly. Apply consistently. And be prepared to explain any outcome your model produces, because you’ll need to.
Frequently Asked Questions
A hybrid judging model combines expert evaluation with public voting so that both professional assessment and audience participation contribute to the awards process. The exact balance depends on the programme design, with expert scores, public votes, or both influencing the final outcome.
When designed well, hybrid models combine the credibility of expert judging with the visibility and engagement generated by public participation.
What are the main types of hybrid award judging models?
Award programmes commonly use four hybrid approaches:
Weighted scoring: Expert scores and public votes are combined using fixed percentages.
Sequential judging: Experts shortlist finalists before public voting determines the winner.
Parallel tracks: Expert judges and public voters select separate winners.
Category-specific models: Different judging methods are used for different award categories.
Each model suits different programme objectives, depending on whether credibility, engagement, or both are prioritised.
The weighting should reflect the programme's priorities. Higher judge weightings emphasise expert credibility, while higher public vote weightings give audiences greater influence over the results. For example, a 70/30 split favours expert evaluation, whereas a 50/50 split gives equal importance to both perspectives.
Publishing the weighting before entries open helps participants understand exactly how winners will be determined.
A sequential model ensures that only high-quality entries reach the public voting stage. Expert judges first identify the strongest submissions, after which the audience chooses the winner from a shortlist of qualified finalists.
This approach maintains credibility while still giving the public a meaningful role in determining the final outcome.
Running expert judging and public voting as separate award categories allows each recognition to retain its own purpose. Expert awards recognise excellence against professional judging criteria, while People's Choice awards reflect audience support.
This avoids confusion over what each award represents and prevents popularity from influencing expert-selected winners.
Common mistakes include failing to publish vote weightings, assigning judging methods that do not match the purpose of a category, giving judges or public voters only token influence, changing the rules during the competition, and creating overly complex systems that participants struggle to understand.
Clear rules and consistent application are essential for maintaining trust in the awards process.
Transparency starts with publishing the judging model before entries open. Organisers should clearly explain how judges score entries, how public votes are counted, how scores are combined, and how winners are selected.
Providing this information upfront builds confidence among entrants, judges, sponsors, and voters while making the final results easier to explain and defend.
A hybrid model works best when an awards programme values both expert credibility and public engagement. If industry recognition and audience participation are equally important, a well-designed hybrid approach can satisfy both objectives without compromising fairness.
However, organisers should only adopt a hybrid model when they can communicate the process clearly, apply it consistently, and confidently justify every possible outcome it produces.