Awards are everywhere now. Recognition programs have multiplied across every industry, region and niche at remarkable speed, and while some of them celebrate genuine excellence, others exist mainly to sell trophies, badges and sponsorship packages. The result is a crowded landscape in which entrants, judges and audiences have all grown more sceptical, and where winning something is no longer enough on its own, people want to understand why it won.
Well-designed awards feel effortless by comparison. The categories are clear, the criteria make sense, the judging model is transparent, and even the people who didn’t win trust the outcome. The difference between the two is structure, and this guide covers how to build it, from defining your purpose through to structuring categories, choosing a judging model, setting eligibility rules and planning a timeline that actually works.
On this page
- What makes an awards program credible
- How the decisions connect
- Defining your purpose
- Designing categories that work
- Setting clear eligibility rules
- Choosing the right judging model
- Planning your timeline
- The structural mistakes that undermine awards
- Why structure affects trust
- The design checklist
What makes an awards program credible
Credibility isn’t a single decision you make but the cumulative result of dozens of small, deliberate ones, most of them taken before anybody submits an entry.
A credible program answers three questions clearly for everyone involved:
- What is being recognised?
- How is it being evaluated?
- Why should the outcome be trusted?
When any one of those is unclear, confidence drains away quickly, and it’s much harder to rebuild than it was to keep. Five things hold those answers up.
Purpose. A credible program knows what excellence looks like in its industry or community and is built to recognise that specific thing consistently, and that purpose then guides everything downstream, from how you create categories to how you weight your criteria.
Transparency. Entrants should understand how their work will be assessed before they submit it, judges should know exactly what they’re being asked to evaluate, and public voters should understand how their votes feed into the result. Where rules, timelines or weightings are vague or hidden, suspicion fills the gap.
Consistency. The same standards have to apply to every entry regardless of who submitted it or who’s judging it, which means clear eligibility rules, defined criteria, a structured scoring system and processes that don’t change halfway through.
Respect for the people involved. Your judges are usually experienced professionals giving their time for free, so asking them to assess poorly structured entries against unclear criteria both lowers the quality of the judging and burns them out. Entrants deserve the same consideration, a process that lets them present their work fairly, without having to guess what judges might be looking for.
Scalability. Whether you receive twenty entries or two thousand, the structure needs to hold and the outcomes need to stay fair, explainable and defensible under scrutiny.
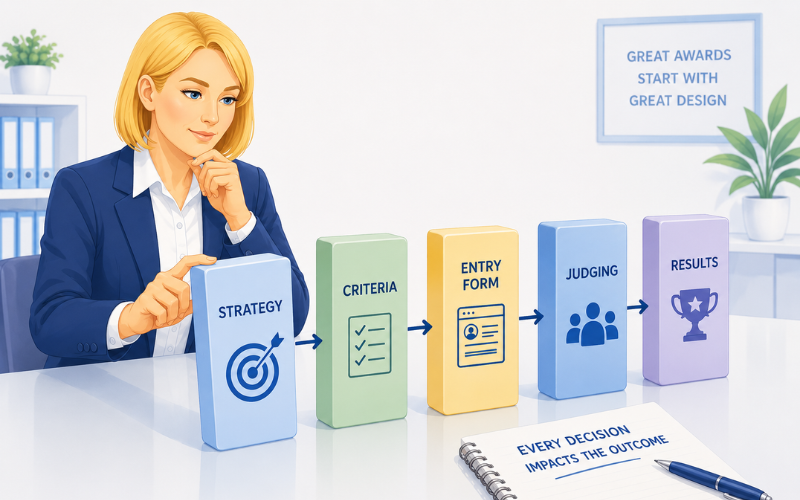
How the decisions connect
Before working through the individual decisions, it’s worth understanding how they relate to each other, because they aren’t separate choices that happen to sit on the same project plan. They’re one system, and pulling on any of them moves all the others.
Laid out in order, the chain runs like this:
- Your strategy defines your audience
- Your audience defines what recognition means to them
- What recognition means defines your categories and criteria
- Your criteria define what information judges need
- What judges need determines your entry questions
- Your questions determine entry length and complexity
- Complexity determines time per entry
- Time per entry determines entries per judge
- Entries per judge determines how many judges you need
- Judge availability determines your timeline
- Your timeline determines when you can announce
- Announcement timing affects how you promote entries
- Promotion affects entry volume
- Entry volume loops back to judging capacity
Programs designed forward from a clear understanding of their audience can make decisions that fit together. They know who they’re serving, what those people need in order to feel recognised, what credible evaluation requires, and what entry design makes that evaluation possible. The timeline comes out of all that, rather than being imposed on it.
The rest of this guide follows that order.
Defining your purpose
Before you design categories, recruit judges or build an entry form, you need to answer something more fundamental: why does this program exist? Purpose is the foundation everything else rests on, and without it programs drift towards vagueness, internal disagreement and outcomes nobody can defend.
The answers don’t need to be sophisticated, but they do need to be clear and shared by everybody running the program, because a purpose only one person can articulate isn’t doing any work.
Purpose as a filter you keep applying
A well-defined purpose makes every later decision easier, since you can test each one against it. When somebody proposes a new category, ask whether it aligns with the purpose. When you’re choosing between judging models, ask which one best reflects what you’re trying to recognise. And when entry numbers are low and somebody suggests loosening the eligibility rules, ask whether that compromises what the award is supposed to mean.
| Vague purpose | Clear purpose |
|---|---|
| “Celebrate excellence in our industry” | “Recognise companies that have measurably improved customer outcomes in the past 12 months” |
| “Honour the best and brightest” | “Highlight emerging professionals under 30 who are shaping the future of sustainable design” |
| “Reward innovation” | “Identify products launched this year that solve a problem in a genuinely new way, as judged by independent technical experts” |
The left column sounds like every awards program that has ever existed, which is precisely the problem, you can’t use any of it to settle an argument about whether a particular entry belongs.
Designing categories that work
Categories are the backbone of the program, because they define what excellence looks like, shape how entrants frame their work, and determine how fairly any two submissions can be compared. Get them right and judging becomes straightforward, whereas get them wrong and you’ve created confusion before a single entry arrives.
Why categories fail
- Overlap. When the same piece of work could reasonably sit in three categories, results become hard to defend, entrants start gaming their placement, and the strongest entries dominate across categories that were meant to recognise different things.
- Buzzwords without boundaries. Labels such as “innovation excellence” or “digital transformation leader” sound impressive while meaning something different to every person who reads them.
- Ambiguous eligibility. Where it isn’t clear who can enter, disputes arrive, and they tend to arrive after judging has started, which is the worst possible moment.
- Too many categories. Programs that add categories every year without ever removing one dilute their own impact, and eventually winning stops feeling distinguishing because so many people did.
Three questions every category must answer
What kind of work belongs here?
Be specific about the type of achievement, project or contribution you’re looking for, so entrants can place themselves accurately without having to guess.
Who is eligible to enter?
Define the restrictions explicitly: company size, geography, experience level, the time period the work falls in.
What distinguishes this from the others?
If you can’t articulate the boundary between this category and the one next to it, the category isn’t ready to publish, and no amount of careful judging will fix that later.
This third question is the one most often skipped, and it’s the one that prevents the overlap problem above.
What good category design looks like
Define by outcome rather than by terminology. State clearly what type of achievement is being recognised instead of reaching for the fashionable phrase, because that helps entrants self-select accurately and ensures your judges are comparing like with like.
Align each category with its judging model. Some achievements need expert evaluation while others genuinely benefit from public sentiment, so design the category with the evaluation method in mind and the scoring will support the category’s purpose rather than distorting it.
Exercise restraint. A short list of well-defined categories almost always outperforms a long list of loosely differentiated ones, and every category should feel meaningful to win.
Review them annually. Categories that made sense three years ago may no longer reflect your industry, so build reassessment into the cycle rather than carrying them forward by default.
Setting clear eligibility rules
Eligibility rules decide who can enter and who can’t, and when they’re clear and consistently enforced they protect the whole program. When they’re vague, they invite exactly the disputes that damage credibility most.
The dimensions to consider
- Organisation size — revenue bands, employee counts, or separate categories for startups and enterprises
- Geography — local, regional, national or international scope
- Time period — work completed or launched within a defined window, such as the past twelve months
- Experience level — emerging professionals against established leaders, or first-time entrants against repeat winners
- Industry or sector — limiting entries to particular verticals or professional fields
- Relationship to you — whether employees, partners or sponsors are permitted to enter at all
Not every program needs restrictions in all six areas, but wherever a boundary exists it has to be explicit.
Why ambiguity causes so much damage
Eligibility disputes are among the most common sources of credibility loss, and the mechanism is always the same. Vague rules get interpreted generously by entrants, that interpretation gets challenged after submission or after judging, and you’re then forced into a decision where both options are bad, disqualifying an entry mid-process feels unfair, while letting a questionable one through undermines the category.
Enforcing consistently
Clear rules only matter if you apply them the same way every time, which means reviewing eligibility at the point of entry rather than after judging, documenting your reasoning whenever an edge case comes up, communicating any disqualification promptly and professionally, and holding a high-profile entrant to exactly the standard you’d hold anybody else to.
That last one is where most programs are tested, and it’s worth deciding your answer before the situation arises rather than in the moment.
Choosing the right judging model
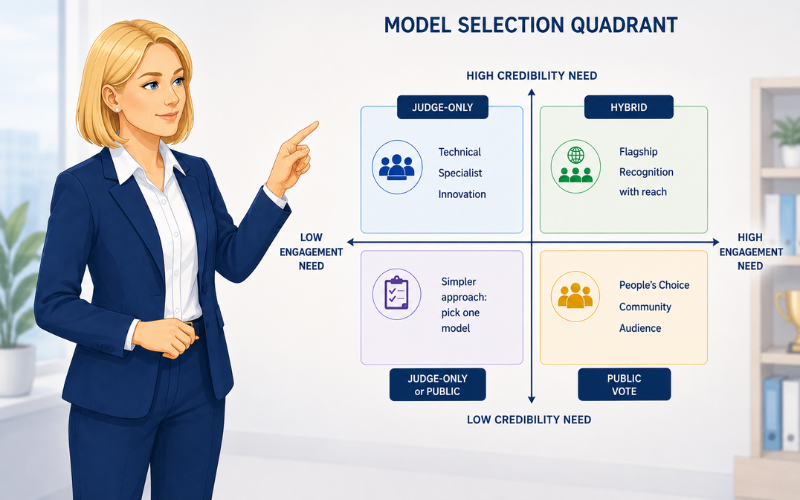
How an award is judged matters as much as what it recognises, because the model shapes perceptions of fairness, changes how entrants behave, and determines how much trust anybody places in the result. There’s no single best model, what matters is choosing the right one for the context and then applying it consistently.
| Model | Best for | Watch out for |
|---|---|---|
| Judge-only | Categories needing deep domain knowledge, technical assessment or nuanced professional judgement | Inconsistency where the criteria or scoring framework are unclear, and judge fatigue where volume is high or entries are poorly structured |
| Public voting | People’s choice categories, community recognition, and anywhere audience engagement is itself the goal | Fraud from click farms and automated voting, and a shift in focus from merit to marketing reach, this should rarely be the sole basis for a winner |
| Hybrid | Programs wanting both credibility and participation, where professional and audience perspectives both genuinely matter | Confusion when public influence is bolted on as an afterthought or the weighting isn’t explained clearly enough for anyone to follow |
If you’re running public voting, technical safeguards aren’t optional. IP validation and email verification are the minimum, and without them the result is only as trustworthy as the least scrupulous entrant.
Four questions to settle before you choose
- What does this category exist to recognise, expertise, popularity, or both?
- Do you have access to qualified judges for this particular subject matter?
- Is public engagement a goal here, or a risk you’d need to manage?
- Can you explain in one sentence how the winner will be determined?
Different categories in the same program can use different models, and that’s often the right answer, a technical innovation category benefits from expert evaluation while an audience favourite category belongs with public voting. For deeper guidance on scoring frameworks, criteria design and reducing bias, see our guide to judging and scoring best practices.
Planning your timeline
A well-designed program can still fail on timing, because rushed judging produces inconsistent decisions, a compressed entry window reduces participation, and a delayed announcement loses momentum and irritates the people who won.
| Phase | What happens | Typical duration |
|---|---|---|
| Design | Define purpose, categories, criteria, eligibility and judging model | 4–8 weeks |
| Launch and promotion | Announce the program, open entries, build awareness | 2–4 weeks before entries open |
| Entry period | Collect submissions | 6–10 weeks |
| Entry review | Screen for eligibility and completeness | 1–2 weeks |
| Judging | Judges evaluate and score | 3–6 weeks |
| Results and verification | Finalise outcomes, notify winners | 1–2 weeks |
| Announcement | Public reveal, ceremony or publication | Fixed date |
These vary with scale and complexity, particularly if your judging involves interviews or multiple rounds, but the principle holds: every phase needs enough time to be done properly.
Does the maths work?
The judging phase is where the cascade usually breaks, and the quickest way to find out is to do the arithmetic before you commit to anything.
Here’s a program that looks entirely reasonable on paper:
- 120 entries expected
- 3 judges per entry, the minimum for reliable scoring
- 25 minutes per entry, moderate complexity
- 12 judges recruited
- 6 hours available from each judge
Hours needed
120 entries x 3 judges x 25 minutes = 9,000 minutes = 150 hours

Hours available
12 judges x 6 hours = 72 hours

Shortfall
150 - 72 = 78 hours
This program doesn’t work. It needs more than twice the judging capacity it has, and nothing in those assumptions looked unreasonable when somebody wrote them down.
When the maths doesn’t balance, something has to change, and every option costs you something:
| If you… | What it costs you |
|---|---|
| Reduce judges per entry | Scores become less reliable. One rushed or biased judge has more influence, outliers are harder to spot, and the result is harder to defend if challenged. |
| Simplify entries | Judges have less to go on. Nuanced achievements become harder to convey, and you may reward concise writers over substantive achievers. |
| Recruit more judges | Qualified people are hard to find, coordination grows, and calibration gets more complex across a bigger panel. |
| Ask judges for more hours | Some decline, some drop out, and the ones who stay get tired. Unrealistic asks produce rushed scoring and damage relationships you’ll need next year. |
| Expect fewer entries | Lower revenue, categories that feel thin, and winners whose achievement means less because the competition was light. |
None of these is automatically wrong. What matters is choosing deliberately, early, rather than discovering the trade-off three days before judging opens. For workload limits by entry complexity, see our guide to judge fatigue and judge experience.
The four timeline mistakes
- Entry windows that are too short. Entrants need time to prepare something good, and a rushed entry hurts the quality of your judging as much as it hurts their chances.
- Underestimating how long judging takes. Your judges are volunteers with day jobs, so asking them to assess fifty entries in a week produces fatigue and inconsistency rather than results.
- Phases with no gap between them. When your entry deadline bumps directly against your judging start date, there’s no room for eligibility review, late submissions or anything unexpected.
- Silent delays. If results slip, say so, because silence erodes trust considerably faster than a revised timeline does.
Experienced organisers build buffer in because they know something will go wrong: a judge drops out, a technical problem delays submissions, or one category receives three times the volume you expected. Put that buffer between entry close and judging, and again between judging and announcement, where the pressure is greatest.
The structural mistakes that undermine awards
Most programs that fail do so because of shortcuts taken early, usually under time pressure and usually with the belief that it can be fixed later. In practice these early decisions shape everything downstream, and once entries are open it’s generally too late to undo them.
Unclear or overcrowded categories. When categories overlap or rely on buzzwords, entrants have to guess where they belong, and judges then struggle to compare submissions that were never meant to compete with each other, producing outcomes that feel subjective rather than earned.
Vague judging criteria. Words such as innovation, impact and excellence sound impressive but mean different things to different judges, so scoring becomes inconsistent and entrants receive conflicting feedback or unexplained results.
Mixed models without clear rules. Public voting and expert judging can coexist perfectly well, but only where the weighting, timing and purpose of each are defined in advance. Layer public voting onto expert judging as an afterthought and you’ll face accusations of popularity bias.
Poorly designed entry processes. Forms that are too open-ended invite vague, generic answers, while forms that are too long produce rushed ones, and either way your judges are left extracting meaning from inconsistent information.
Over-reliance on manual processes. Spreadsheets, email threads and ad hoc rule changes introduce inconsistency and human error, and as the program grows these stopgaps stop being merely inefficient and become a genuine risk to fairness.
None of these is dramatic on its own. Together they produce a program that feels confusing and unreliable to everybody who touches it.
Why structure affects trust
Trust builds gradually, through every interaction somebody has with your process. Where a program is well structured, expectations are clear from the outset: entrants understand what’s being judged and how to present their work, judges know exactly what they’re evaluating and why, public voters can see how their participation fits in, and even the people who didn’t win can follow the logic of the outcome.
Where structure is weak, trust erodes quietly and fast. Confusing categories produce questionable comparisons, vague criteria invite subjective scoring, last-minute rule changes raise doubts about fairness, and manual processes introduce errors that are difficult to explain afterwards. Over time these stop being problems with individual results and become the reputation of the awards themselves.
Structure also protects you. Clear frameworks reduce disputes, minimise complaints and make decisions defensible under scrutiny, and when an outcome can be explained calmly and consistently, confidence tends to replace tension.
The design checklist
Designing a credible awards program
Purpose and strategy
- Purpose is clearly defined and documented
- Target audience identified: who enters, who judges, who cares about the winners
- Success metrics established, covering participation, reputation and engagement
Category design
- Each category has a clear, distinct focus
- No significant overlap between categories
- Categories aligned with their intended judging models
- Category count is restrained and justified
Eligibility
- Eligibility rules are explicit for each category
- Rules cover size, geography, time period and any other restrictions
- Enforcement process is defined before entries open
Judging model
- Model chosen deliberately for each category
- Weightings defined and communicated, where the model is hybrid
- Judges briefed on criteria and expectations
- Conflict of interest policy in place
Capacity
- Judging hours needed calculated against hours available
- Entries per judge within sustainable limits
- Shortfall resolved before entries open, not after
Criteria and scoring
- Judging criteria defined with clear, shared meaning
- Scoring model documented and applied consistently
- Criteria aligned with the entry form questions
Entry process
- Entry form questions map to judging criteria
- Word limits and guidance encourage clarity
- Entry format consistent across all submissions
Timeline
- Timeline includes every phase with realistic durations
- Buffer built in between phases
- Announcement date confirmed and protected
Communication
- Rules and process published before entries open
- Judges, entrants and voters understand their roles
- Results communication plan prepared
Structure is what makes the case for you
Everything in this guide comes back to a single idea: the decisions you make before entries open determine whether anybody believes your results afterwards.
That’s why the order matters more than any individual choice. A program can survive a category that didn’t quite land or a judging window that ran a week long. What it can’t survive is a structure that was never coherent, where the categories don’t match the criteria, the criteria don’t match the entry form, and the judging capacity was never checked against the entry volume.
Get the sequence right and you won’t need to convince anybody your awards are fair, because the process will demonstrate it on your behalf. Get it wrong and no amount of messaging will recover the position, since the people who doubt your results will be pointing at structural gaps you can no longer close.
Continue learning
- Judging and scoring best practices — how to design criteria, scoring models and workflows that produce fair, defensible results.
- Judge fatigue and judge experience — workload limits by entry complexity, and how to design judging your panel can sustain.
- Entries, storytelling and quality control — how to structure entry processes that surface clarity and evidence.
- Public voting and awards engagement — when public voting works, when it backfires, and how to balance reach against trust.
Frequently Asked Questions
Defining a clear purpose ensures the awards program knows exactly what it is recognising and why it exists. A well-articulated purpose acts as a decision-making filter for categories, eligibility rules, judging models, and criteria, preventing the program from drifting into vague or inconsistent territory.
When purpose is unclear, categories become broad, criteria become subjective, and outcomes are harder to defend. A specific purpose, such as recognising measurable customer impact within a defined timeframe, creates alignment across every stage of the awards process and strengthens long-term credibility.
The most common category design mistakes include overlap between categories, reliance on buzzwords without clear definitions, ambiguous eligibility, and creating too many categories over time. These issues make it difficult for entrants to know where to apply and for judges to compare submissions fairly.
Strong categories clearly define what type of work belongs, who is eligible, and how the category differs from others. Fewer, well-defined categories typically carry more prestige and lead to more defensible outcomes than long, loosely structured lists.
Unclear eligibility rules create disputes that often surface after submissions are received or judging has begun. When entrants interpret vague rules differently, organisers are forced to either disqualify entries mid-process or allow questionable submissions to stand, both of which undermine trust.
Explicit eligibility criteria covering factors such as geography, organisation size, time period, and restrictions protect fairness. Reviewing eligibility at the point of entry and applying rules consistently to all participants helps prevent reputational damage.
udge-only models are best suited for technical or specialist categories where expert evaluation is essential. Public voting models work well for audience-driven or “people’s choice” awards where engagement and sentiment are part of the intended outcome. Hybrid models combine both approaches and can balance credibility with participation when weightings are clearly defined.
The key is alignment. The judging model should reinforce what the category is designed to recognise. Introducing public voting into expertise-driven categories without clear safeguards can shift focus from merit to popularity and weaken trust.
An unrealistic timeline can compromise even a well-designed awards program. Short entry windows reduce submission quality, rushed judging leads to inconsistent scoring, and delayed announcements frustrate participants.
A structured timeline should include defined phases for design, promotion, entry collection, eligibility review, judging, verification, and announcement, with buffer time built between key stages. Working backward from the announcement date helps ensure each phase has adequate time to be executed properly.
Judging criteria such as “innovation” or “excellence” can mean different things to different judges if they are not clearly defined. Without shared definitions and structured scoring frameworks, evaluations become subjective and inconsistent across submissions.
Clear, documented criteria aligned with entry form questions ensure judges are assessing the same qualities in the same way. This consistency makes outcomes easier to explain and more likely to be accepted, even by those who do not win.
Structural weaknesses often include overlapping categories, unclear criteria, mixed judging models without defined weightings, poorly designed entry forms, and over-reliance on manual processes like spreadsheets and email threads.
Individually, these issues may seem minor. Combined, they create confusion, fatigue, and preventable errors. A structured framework applied consistently across categories, judging, eligibility, and communication reduces disputes and strengthens long-term reputation.
Strong structure improves entry quality, supports consistent judging, and produces outcomes that participants can understand and accept. Clear expectations reduce disputes, while documented processes make decisions defensible under scrutiny.
Over time, this consistency builds compounding trust. Participants are more likely to enter again, judges are more willing to contribute their expertise, and winners carry recognition that is respected rather than questioned.