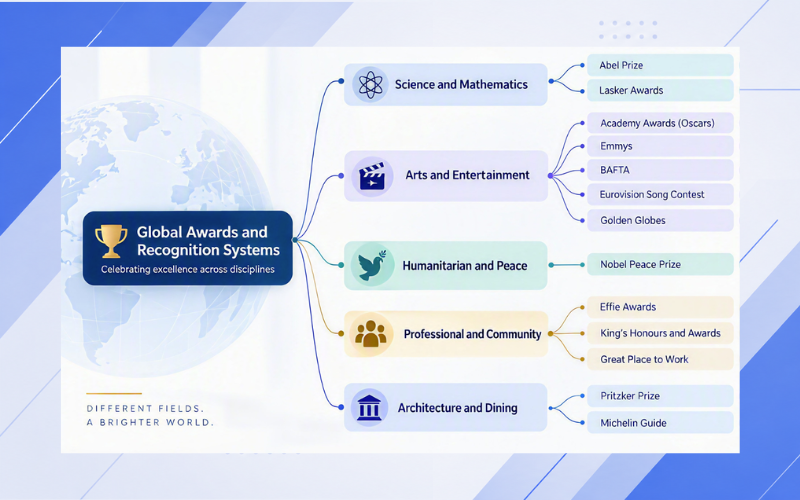
The world’s most respected awards cannot be applied for because the route to winning involves being noticed rather than applying.
Nobody submits an entry form for a Nobel Prize, and no restaurant owner fills out an application for a Michelin star. The Pritzker Architecture Prize, the MacArthur Fellowship, the Lasker Award, these are bestowed rather than pursued, and recipients often find out they’ve won when the phone rings.
This guide walks through how the major recognition models operate, from the awards you can’t enter through to the rating systems that behave like awards, and what each one does to earn the authority it has.
On this page
- The five models at a glance
- Awards you cannot enter
- Awards judged on proven results
- Awards decided by the crowd
- Peer academy awards
- Rating systems that behave like awards
- The credibility pattern
- What this means for your program
The five models at a glance
Recognition programs find excellence in five broadly different ways, and each model buys its credibility with something different.
| Model | How excellence is found | Where the credibility comes from | Examples |
|---|---|---|---|
| Nomination only | Observation, peer nomination or independent investigation, candidates cannot put themselves forward | Complete independence from the candidate, which removes any route to lobbying | Nobel, Michelin, Pritzker, MacArthur, Lasker, Abel |
| Evidence-led entry | Entrants apply, but must document results rather than describe them | Verification built into the process, often against external records | Effie, Deming, Baldrige, King’s Awards for Enterprise |
| Public vote | The audience decides, either alone or alongside a jury | Transparency about how votes translate into outcomes | Eurovision, The Game Awards, People’s Choice |
| Peer academy | A closed membership body of practitioners votes within its own profession | The informed judgement of people who understand the craft | Oscars, Emmys, Tonys, BAFTAs, Cannes Lions |
| Ongoing rating | Continuous assessment against a standard rather than an annual contest | Conditionality, the recognition can be lost | B Corp, Great Place to Work, World’s 50 Best |
Awards you cannot enter
At the top of the credibility ladder sit the awards where self-nomination is impossible, because these programs locate excellence through observation, peer nomination or independent investigation rather than by waiting for submissions to arrive.
Michelin stars are perhaps the purest version of the model. Anonymous inspectors visit restaurants without warning, pay their own bills and file detailed reports, so a restaurant can’t request consideration, can’t prepare for the visit, and frequently has no idea it’s being assessed at all. The star arrives, or doesn’t, based on what the inspectors experienced as ordinary diners. The process is expensive and doesn’t scale, and yet it produces recognition the industry treats as definitive, a star can transform a restaurant’s economics overnight, and losing one can close it.
The Nobel Prize works through confidential nomination, where previous laureates, university professors and other qualified nominators submit names to the relevant committee. Self-nomination is explicitly prohibited, and the deliberations stay sealed for fifty years. When the call comes from Stockholm it usually recognises work done over decades, and that long gap between discovery and prize is deliberate, because it lets the committee assess lasting impact rather than recent headlines.
The Abel Prize in mathematics and the Lasker Award in medicine follow the same pattern of peer nomination and closed deliberation with no application process. The Lasker is often called America’s Nobel, partly because so many recipients go on to win in Stockholm, and its credibility comes precisely from its inaccessibility, there is no shortlist you can lobby your way onto.
The Ballon d’Or achieves a similar insulation by a different route, since international football journalists vote on the basis of what they’ve watched across a season. Players don’t submit highlight reels or evidence packages, so the recognition reflects observed performance, argued about publicly and voted on privately by people whose job is watching football.
Awards judged on proven results
A second tier does accept entries, but demands evidence rigorous enough that the submission itself becomes a verification exercise.
The Effie Awards for marketing effectiveness are the gold standard here, because creative excellence counts for nothing without proof that the work moved business metrics. Entries have to demonstrate measurable outcomes with data, sales increases, market share gains, behavioural change, which means a beautiful campaign that won creative awards elsewhere will lose an Effie to an unremarkable-looking one that demonstrably worked.
That inversion, where substance defeats style, is exactly what makes an Effie mean something, since everybody in the industry knows you can’t win one by describing success. You have to document it.
The Deming Prize in Japan and the Baldrige Award in the United States push verification further still, because these national quality awards don’t merely review submissions, they audit them. Assessors visit your facilities, interview your employees and examine your operations first-hand, so the written application is the start of the evaluation rather than the end of it. You can’t fabricate a quality culture that doesn’t exist, because the assessors will notice when they walk your floor.
The King’s Awards for Enterprise in the UK require multi-year verified financial data, with claims about growth, exports or sustainable development cross-checked against Companies House filings, tax records and other government departments. The application asks for data applicants can’t invent, because it already exists in official records, verification is baked into the design rather than bolted on afterwards.
Awards decided by the crowd
Public voting creates a different kind of legitimacy, democratic rather than expert, and its credibility depends entirely on the integrity of the voting process and the transparency of how crowd input becomes an outcome.
Eurovision is the hybrid model at its most theatrical. Juries of music professionals supply roughly half the points and public televoting supplies the other half, and the tension between the two camps, professionals rewarding craft, audiences rewarding spectacle, generates much of the drama. Juries and publics regularly hand their top marks to different countries, which exposes how differently experts and audiences assess the same performances, and that visible disagreement paradoxically strengthens the contest’s credibility. Nobody can claim the fix is in when both methodologies are published side by side.
It’s also a useful illustration of how a voting system evolves under scrutiny. For 2026 the EBU restored juries to the semi-finals, expanded each jury from five members to seven, widened the range of professional backgrounds jurors can be drawn from, halved the number of votes any individual can cast per payment method, and tightened its rules on third-party promotional campaigns.
The Game Awards weight jury votes at roughly ninety per cent and let public voting contribute the rest, which is a deliberate design choice rather than an accident. The organisers want audience participation for the engagement it brings, but not so much of it that popular franchises with large fanbases automatically beat smaller, critically acclaimed titles. The public vote supplies legitimacy without determining the outcome.
People’s Choice Awards sit at the other extreme, as pure public voting with no expert filter, and their standing within the industry is correspondingly modest. Winning one demonstrates popularity with the audience who chose to vote rather than excellence as assessed by professionals, which isn’t worthless, since popularity is a genuine form of validation, but it occupies a different place in the hierarchy.
The pattern is straightforward. The more an outcome depends on mobilising votes, the less it depends on demonstrating excellence, so public voting awards optimise for engagement and accessibility while expert-judged awards optimise for discrimination and credibility. Both have value, and they serve different purposes.
Peer academy awards
The Academy Awards created a template that plenty of industries have since adopted: a closed membership organisation whose members vote on excellence within their own profession.
The Oscars, Emmys, Tonys and BAFTAs all work this way, with selective membership that usually requires demonstrated professional achievement. The theory is that practitioners understand best what excellence looks like in their own craft, and that peer validation carries more weight than an outsider’s judgement.
What peer voting gets right
Peer voters genuinely understand the difficulty of what nominees pulled off. A cinematographer assessing camera work, an editor judging editing, an actor evaluating a performance, these are informed opinions in a way that outside judgement rarely is.
What it gets wrong
Peer voting also creates insularity, since academy voters skew older, may favour familiar styles, and can be swayed by campaigning. The intensive marketing around Oscar season tells you how much studios believe exposure shapes peer perception.
Cannes’ Palme d’Or takes a different route, using a small hand-picked jury rather than a large voting academy, with each year’s panel of directors, actors and critics selected by the festival. That produces more variable outcomes, because a given jury might champion challenging work another would have passed over, but it also produces genuine curatorial vision. The Palme represents what one particular group of respected voices found most valuable rather than a poll of industry consensus.
Cannes Lions and D&AD add entry fees to the peer-jury model, so agencies pay to submit work and expert juries evaluate it. The commercial element is explicit, these are industry awards that help agencies market themselves, funded by agencies’ willingness to pay, and the credibility rests on jury composition and scoring rigour rather than on exclusivity. When the same campaign wins across several shows, the consistency validates it; when the wins look disconnected from merit, scepticism follows.
Rating systems that behave like awards
Some programs blur the line between an award and a certification, providing an ongoing rating rather than an annual honour.
World’s 50 Best Restaurants operates as a philosophical rival to Michelin, using a voting academy of more than a thousand industry voters, chefs, food writers, restaurateurs, casting ballots based on their own dining experiences rather than relying on anonymous inspectors. The methodology is more transparent than Michelin’s but correspondingly more vulnerable to campaigning, because voters are known to the organisers even where they aren’t known to the public, so restaurants can attempt to influence them. That tension between democratic breadth and susceptibility to influence defines the program’s ongoing credibility debates.
B Corp certification functions more like an audit than an award. Companies complete a detailed assessment covering governance, workers, community, environment and customers, assessors verify the claims against documentation, and certification has to be renewed on a three-year cycle. The recognition isn’t competitive, since any company meeting the standard can earn it, but the standard is demanding enough to mean something, and it’s become more so, because the revised standards rolling out from 2026 require companies to meet minimum requirements across every impact area rather than simply clearing an overall points threshold, with more third-party verification and a requirement to demonstrate continuous improvement over time.
Great Place to Work certification similarly rests on employee surveys and audited claims rather than self-submitted narrative, measuring what employees actually report about their workplace and providing a check against the employer’s own description of its culture.
The credibility pattern
Across all of these, the pattern that emerges is that the more you can buy your way in, the less the award is worth.
The awards at the top, Nobel, Michelin, Pritzker, MacArthur, are nominated rather than entered, with no fee, no submission and no involvement from anybody’s marketing department. Recognition finds you instead of you pursuing it.
The awards that charge entry fees sit lower on the ladder, and everybody in every industry knows it. That isn’t because entry fees are inherently corrupting, but because the entry model creates opportunities for gaming that the nomination model simply eliminates:
- When you can choose to enter, you can tailor your submission to what you think will win
- When you can pay, you can outspend the people who can’t
- When there’s a deadline, there’s a campaign
Each of those introduces friction between what an organisation actually achieved and how that achievement gets perceived.
On the other hand for entry-based awards they have to earn credibility through process rather than through exclusivity, and the examples above show it can be done. The Effies prove an entry-based program can be rigorous as long as the evidence it demands actually matters. The King’s Awards demonstrate that claims can be verified against external records. Baldrige shows that an on-site assessment turns a written submission from a claim into something auditable.
What this means for your program
If you’re building or running an awards program, the lesson is that your credibility comes from what happens after the entry arrives.
Accepting submissions means compensating for the self-selection that creates, and there are three questions worth being able to answer. If anyone can enter, what stops entries being aspirational rather than accurate? If marketing teams write the submissions, how do your judges tell substance from style? And if entry fees fund the program, how do you keep commercial pressure away from the outcomes?
How rigorous programs answer
They require evidence rather than description. They verify claims against external sources. They use judges with both expertise and independence, declare conflicts publicly and manage them transparently.
And structurally
They score against published criteria rather than subjective impression, and they keep commercial operations separate from judging decisions, so that nobody selling sponsorship has any influence over who wins.
None of this closes the gap between entry-based and nomination-based recognition entirely. It narrows it enough that the award means something. When everybody can see the rules were followed, when winners can point to the evidence that earned the result, and when the entrants who lost can identify where they fell short, then an entry-based award has earned its credibility the hard way.
That’s worth more than it sounds, because a program with that reputation attracts the entrants who have real results to show, and once that happens, the quality of your winners does the rest of the work for you.